MAESTRO Framework: A 7-Layer Field Guide to Agentic AI Threat Modeling
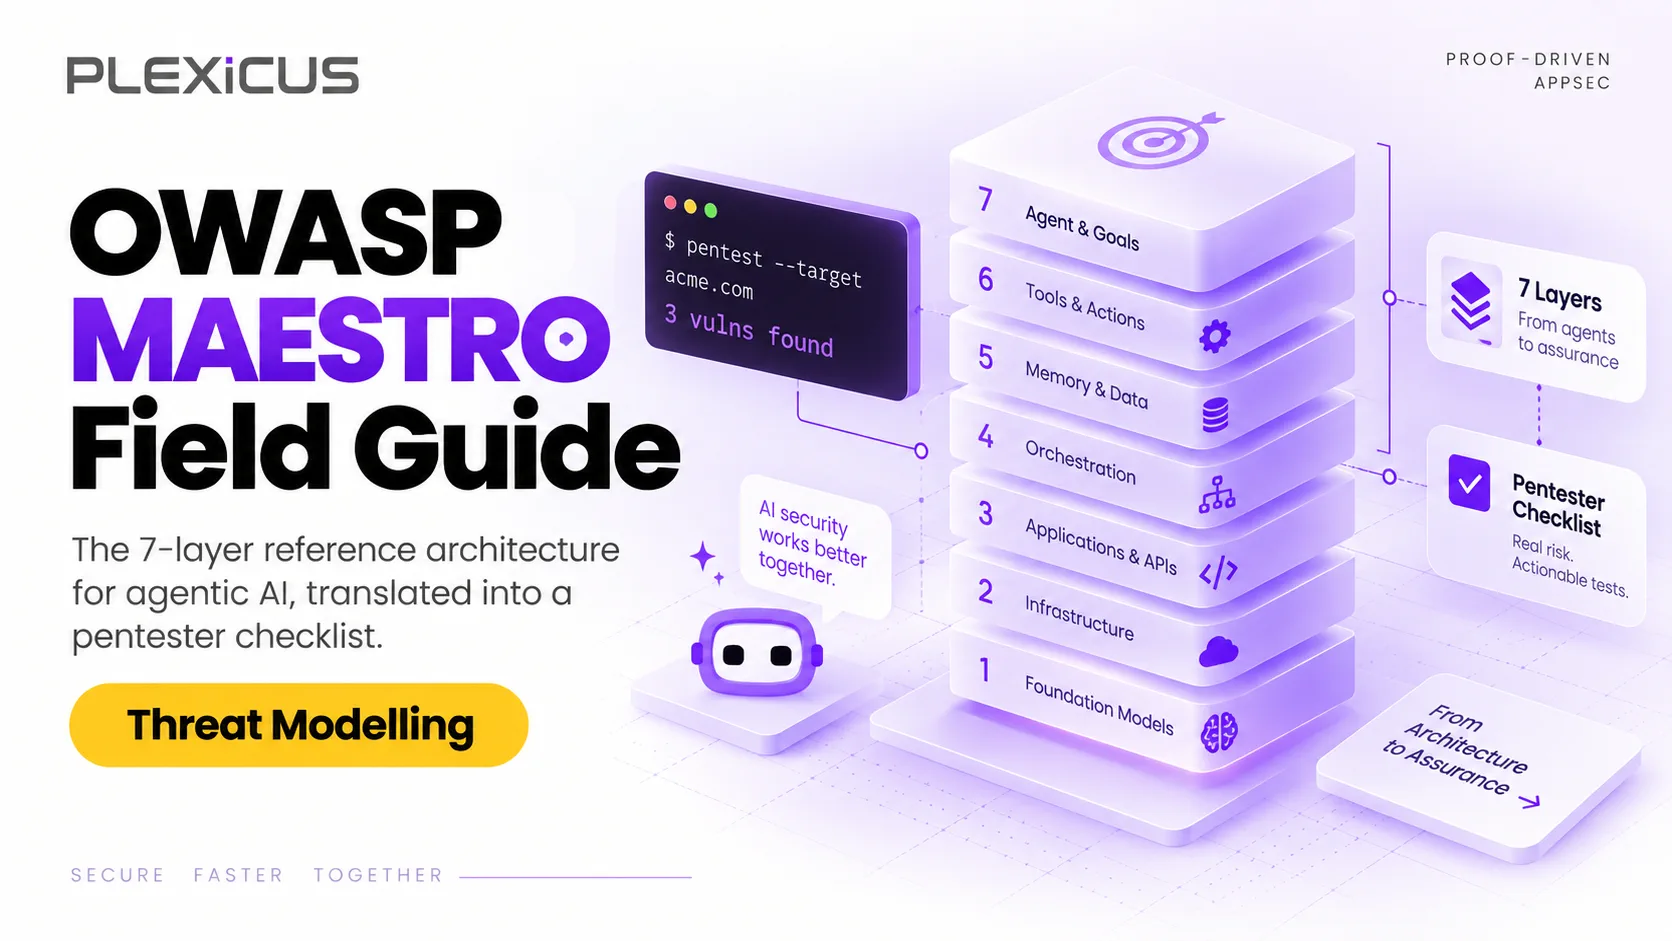
MAESTRO is the Cloud Security Alliance's 7-layer framework for agentic AI threat modeling, applied by the OWASP GenAI Security Project. This guide turns each layer into a pentest checklist.
Beyond ASPM
Proof-Driven AppSec for teams building with AI
Plexicus uses AI Swarm Pentest to explore authorized application paths, validate what is exploitable, and give teams evidence they can use to prioritize remediation.
Explore AI Swarm PentestThe MAESTRO framework (Multi-Agent Environment, Security, Threat, Risk, and Outcome) is a seven-layer threat modeling method for agentic AI systems. Ken Huang introduced it through the Cloud Security Alliance in February 2025, and the OWASP GenAI Security Project’s Multi-Agentic System Threat Modeling Guide (April 2025) is built around it, which is why many teams call it “OWASP MAESTRO.” This field guide turns each MAESTRO layer into a pentester’s checklist.
Every threat modelling framework your security team has used so far was built for software that humans wrote. STRIDE targets classic application threats. PASTA is a risk-centric, attack-simulation process. LINDDUN covers privacy threats. OCTAVE is for organisational risk. Trike and VAST focus on scaling threat modelling across teams.
None of them model the threat surface of an agent. None of them have a layer for “the model’s training data was poisoned.” None of them have a layer for “the agent’s tool description was rewritten after approval.” None of them have a layer for “the agent’s reasoning trace diverged from its stated goal.”
MAESTRO was written for that gap. Rather than throwing the older methods away, the CSA authors extend categories from STRIDE, PASTA, and LINDDUN with AI-specific threats and organise them layer by layer. The rest of this guide gives you concrete attack patterns, detection signals, and mitigations per layer.
What Is the MAESTRO Framework?
MAESTRO is a 7-layer reference architecture for agentic AI security. It keeps the useful parts of STRIDE and PASTA but models the threat surface bottom-up, for what emerges when an AI agent has:
- A persistent memory
- Tool-calling capabilities (often through MCP)
- A multi-step reasoning loop
- The ability to act on external systems
The seven layers, bottom to top:
- Foundation Models — the LLMs that power the agent
- Data Operations — the pipelines that feed context into the model
- Agent Frameworks — the runtime that orchestrates the agent loop
- Deployment & Infrastructure — where the agent runs
- Evaluation & Observability — how the agent’s behaviour is measured and logged
- Security & Compliance — the controls that govern the agent
- Agent Ecosystem — the other agents, tools, and services the agent interacts with
In the CSA original, Security & Compliance is a vertical layer that cuts across the other six rather than sitting on top of them. Each layer has its own threat model, its own attack patterns, and its own mitigations. Generic threat models tend to collapse most of this into a single “external dependencies” bucket. MAESTRO separates them.
MAESTRO vs OWASP: who publishes what
- Cloud Security Alliance (CSA): original MAESTRO framework post by Ken Huang, February 6, 2025.
- OWASP GenAI Security Project, Agentic Security Initiative: the Agentic AI Threats and Mitigations taxonomy (February 2025) and the Multi-Agentic System Threat Modeling Guide (April 2025), which applies MAESTRO to real multi-agent systems.
The result is a framework that an agentic-AI pentester can use as a checklist. The rest of this guide is that checklist.
Layer 1 — Foundation Models
Threat surface
The model itself, its weights, its training data, and the supply chain that produced it.
Attack patterns
- Model poisoning via training data. A dataset contributor injects backdoored examples. The model learns the trigger. The trigger is activated in production.
- Weight exfiltration. An attacker compromises the model registry and copies the weights. The model is now available to competitors or for adversarial fine-tuning.
- Backdoored checkpoints on Hugging Face. A publicly available fine-tune of a known model contains a backdoor. The downstream agent inherits it.
- Adversarial fine-tuning of an open-source base. A team uses Llama 4 or Mistral as a base. An attacker publishes a “safety-tuned” variant that has been subtly misaligned. The team picks the wrong one.
Detection signals
- Hash mismatch between expected and loaded weights
- Suspicious gradient updates during fine-tuning
- Downstream behaviour that triggers on rare inputs (probabilistic backdoor detection)
- Unusual loss-curve spikes during training
Mitigations
- Pin model versions by hash, not by name
- Source weights from attested registries (Hugging Face signed commits, internal signed artefacts)
- Run adversarial-robustness evaluation before deployment
- Maintain an allowlist of model providers with provenance verification
Layer 2 — Data Operations
Threat surface
The data the agent consumes at runtime: retrieval-augmented generation (RAG) corpora, prompt templates, conversation history, tool outputs, and any other context that flows into the model at inference time.
Attack patterns
- Indirect prompt injection via RAG documents. OWASP LLM01 defines indirect prompt injection as input the model accepts from external sources such as websites or files. The attacker plants text in a document the agent will retrieve. The text contains instructions the agent follows as if they came from the user.
- Prompt template smuggling. The attacker modifies a stored prompt template to include additional instructions that bypass the agent’s safety layer.
- Tool-output poisoning. The agent calls a tool. The tool returns a string that contains injected instructions. The agent treats the tool output as a trusted instruction source.
- Memory poisoning. The agent writes to its long-term memory. The attacker can write to the same memory store (often a vector database). Future retrievals include the attacker’s instructions.
- Log injection. The agent logs its reasoning trace. The attacker injects text into the log. A monitoring agent reads the log and treats the injected text as instructions.
Detection signals
- Tool outputs that contain instruction-like patterns (imperative voice, second-person address)
- RAG documents with unusually high instruction density
- Memory writes that do not match the agent’s observed interaction history
- Log entries that contain language patterns inconsistent with the agent’s persona
Mitigations
- Treat all retrieved content and tool outputs as untrusted data, not instructions
- Use a separate instruction channel (system prompt) that is isolated from the data channel
- Sandbox tool outputs through a structured parser, not raw string concatenation
- Apply provenance tracking to every memory write
Layer 3 — Agent Frameworks
Threat surface
The runtime that orchestrates the agent loop: the planning module, the tool-selection logic, the memory interface, the reasoning trace, and the execution scheduler.
Attack patterns
- Reasoning trace manipulation. The agent’s chain-of-thought is exposed in logs. The attacker reads the trace, identifies the goal, and plants a misleading observation that redirects the next step.
- Tool-selection hijacking. The agent selects tools based on a planner. The attacker registers a malicious tool with a name similar to a legitimate one. The planner picks the wrong tool.
- Loop amplification (denial of wallet). The agent enters a reasoning loop that costs API tokens. The loop runs indefinitely until the budget is exhausted.
- Sub-agent escape. A supervisor agent spawns a sub-agent. The sub-agent has fewer constraints than the supervisor. The sub-agent performs actions the supervisor would not have approved.
- Reasoning-vs-action drift. The agent’s stated reasoning diverges from its actual actions. The auditor reads the trace and sees no problem. The actions tell a different story.
Detection signals
- Reasoning traces that contain language inconsistent with the agent’s persona or goals
- Tool selections that do not match the agent’s stated plan
- Token spend anomalies per agent invocation
- Sub-agent invocations that exceed the supervisor’s stated budget
- Discrepancy between trace and action logs
Mitigations
- Sandbox the planning module from the execution module
- Require explicit confirmation for tool invocations outside an allowlist
- Cap token spend per invocation and per session
- Maintain a strict supervisor/sub-agent hierarchy with capability inheritance rules
- Compare reasoning traces against action logs as a continuous check
Layer 4 — Deployment & Infrastructure
Threat surface
The runtime environment where the agent executes: containers, serverless functions, VMs, the underlying operating system, the secrets used by the agent, and the network paths the agent can reach.
Attack patterns
- Container escape. The agent runs in a container. A vulnerability in the container runtime allows escape to the host. The agent now has the host’s privileges.
- Credential theft from runtime. The agent has API keys, database credentials, or OAuth tokens in its environment. A tool-output prompt injection causes the agent to exfiltrate them.
- Lateral movement to internal services. The agent has network reach to internal services. The attacker uses the agent as a pivot point.
- Persistent runtime backdoor. The attacker installs a backdoor in the agent’s container image. Every redeployment re-introduces it.
- Side-channel data leakage. The agent’s compute patterns (timing, GPU utilisation) leak information about the prompt or the model’s state.
Detection signals
- Unexpected outbound connections from the agent’s runtime
- Unusual file system or network activity
- Container drift from the known-good image
- Discrepancy between declared and actual egress rules
Mitigations
- Run the agent with the minimum privileges required (read-only file systems, no outbound network except to allowlisted endpoints)
- Source container images from attested registries with hash pinning
- Use network policies to enforce egress allowlists
- Rotate credentials on every agent restart
- Deploy runtime threat detection (e.g., Falco, Tetragon) on the agent’s host
Layer 5 — Evaluation & Observability
Threat surface
The telemetry, logging, evaluation, and observability infrastructure that monitors the agent.
Attack patterns
- Log poisoning. The agent’s logs include the tool outputs. The attacker injects text into a tool output that flows into the logs. The SIEM ingests the log and treats the injected text as an alert description.
- Telemetry spoofing. The agent’s evaluator reports metrics that look healthy. The metrics are fabricated. The agent is misbehaving.
- Eval set poisoning. The evaluation dataset is stored in the same place as production data. The attacker modifies the eval set. The agent “passes” evaluations that no longer reflect real behaviour.
- Evaluator-agent collusion. A separate agent evaluates the production agent. Both are reachable from the same prompt-injection sink. The attacker uses the sink to manipulate the evaluator.
Detection signals
- Log entries that contain language patterns inconsistent with the agent
- Sudden metric improvements that do not match operational changes
- Eval set hashes that change without a corresponding code or data commit
- Discrepancy between evaluator output and ground-truth observations
Mitigations
- Separate the logging channel from the agent’s data channel
- Sign and hash all eval sets; alert on hash drift
- Treat evaluator outputs as untrusted; cross-check with raw telemetry
- Use external ground-truth signals (e.g., user feedback, system-of-record diffs) to validate eval results
Layer 6 — Security & Compliance
Threat surface
The controls, policies, and compliance regimes that govern the agent’s behaviour: RBAC, scope enforcement, audit logging, human-in-the-loop approval, and the policy-as-code artefacts that encode the rules.
Attack patterns
- Scope escalation via tool composition. Each tool the agent uses has a narrow scope. The agent chains tools in a way that the composition has a broader scope than any individual tool.
- Human-in-the-loop bypass. The approval workflow assumes a human will reject a dangerous action. The agent generates a confusing description of the action. The human approves.
- Policy-as-code injection. The policy engine reads rules from a versioned artefact. The attacker modifies the artefact. The agent now operates under new rules.
- Audit log tampering. The agent has access to its own audit log. The attacker uses the agent to rewrite the log to cover tracks.
Detection signals
- Tool invocations that exceed the declared scope of any single tool
- Approval patterns inconsistent with the agent’s stated action
- Policy artefact hash changes without a corresponding commit
- Audit log entries that are modified post-hoc
Mitigations
- Apply capability checks at the composition level, not just the individual tool level
- Require plain-language summaries of the action alongside the action itself
- Sign and hash policy artefacts; alert on drift
- Write audit logs to an append-only store the agent cannot access
Layer 7 — Agent Ecosystem
Threat surface
The other agents, tools, MCP servers, external services, and humans that the production agent interacts with.
Attack patterns
- MCP tool poisoning. The MCP server changes its tool description after the agent has approved it (a “rug pull,” documented by Invariant Labs). The new description contains different behaviour.
- MCP server compromise. The MCP server itself is compromised. The agent’s tool calls now route through attacker-controlled code.
- Cross-agent prompt injection. Agent A and Agent B communicate. Attacker plants instructions in A’s context that target B specifically.
- Tool marketplace supply chain. A community-published tool contains malicious code. The agent imports it. The tool exfiltrates credentials at first use.
- Human impersonation. The agent receives a message that appears to be from a human operator. The operator is actually the attacker. The agent follows the instructions.
Detection signals
- Tool description drift after approval
- Unexpected behaviour changes in long-running tools
- Cross-agent messages with instruction-like content
- Tools from marketplaces with low provenance scores
- Operator messages with anomalous patterns
Mitigations
- Pin MCP tool descriptions at approval time; alert on drift
- Use a tool allowlist with provenance requirements
- Sandbox cross-agent communication through structured messages
- Require multi-factor authentication for operator instructions
- Maintain a tool inventory with risk scores
A Worked Example — Hexstrike-AI
In September 2025, Check Point reported that threat actors were discussing Hexstrike-AI, an offensive framework whose FastMCP server connects LLMs (Claude, GPT, Copilot) to more than 150 security tools, as a way to exploit the Citrix NetScaler flaws CVE-2025-7775, CVE-2025-7776, and CVE-2025-8424 disclosed on August 26, 2025. Forum posts claimed it cut time-to-exploit from days to under 10 minutes.
Hexstrike-AI is the attacker’s agent, not the victim. That makes it a good MAESTRO exercise: if an agent with the same design ran inside your estate, as a red-team tool or an internal automation agent with the same tool reach, what would each layer have to answer? The table below is our illustrative mapping, not findings from the Check Point report.
| MAESTRO layer | Questions an agent like Hexstrike-AI raises |
|---|---|
| L1 — Foundation Models | It relies on third-party LLMs; model behaviour and guardrails sit outside your control |
| L2 — Data Operations | Scan results and tool output flow back into the model context, an indirect prompt injection path from hostile targets |
| L3 — Agent Frameworks | The orchestrator picks from 150+ tools; look-alike or hijacked tools would redirect it |
| L4 — Deployment & Infrastructure | Wherever the MCP server runs, its network reach and credentials make it a pivot point |
| L5 — Evaluation & Observability | Without per-tool-call logs, an automated scan-and-exploit run is hard to reconstruct |
| L6 — Security & Compliance | Scope is enforced by the operator, not the tool; nothing stops a chained exploit from leaving the authorized targets |
| L7 — Agent Ecosystem | The MCP layer is the main attack surface; tool descriptions and community tools need pinning and provenance |
The MAESTRO mapping makes the threat surface legible at every layer. A pentester working a similar agent has a checklist that walks bottom-up. The same pattern of agents wired to real tools shows up in mainstream platforms too; our breakdown of the OpenAI DevDay 2026 agent stack looks at it from the defender’s side.
MAESTRO Threat Modeling Checklist for Pentesters
For each layer, before you start a pentest engagement against an agentic AI system, confirm:
- L1 — Models: What models power the agent? What is the provenance? Are weights pinned?
- L2 — Data: What is the agent reading at runtime? Is retrieved content treated as instructions or as data?
- L3 — Frameworks: Is there a separate planner and executor? Are sub-agent capabilities inherited or scoped?
- L4 — Infrastructure: What are the runtime privileges? What is the egress policy? Is the image attested?
- L5 — Telemetry: What is logged? Where do logs flow? Can the agent write to its own audit log?
- L6 — Controls: How is scope enforced at the composition level? Where do human approvals happen?
- L7 — Ecosystem: What MCP servers does the agent use? Are tool descriptions pinned? What other agents does it communicate with?
This is the bar. Every engagement that does not cover all seven layers is a partial engagement. If you are choosing tooling for that engagement, our comparison of AI penetration testing tools sorts the market by evidence quality, and Plexicus AI Swarm Pentest runs signed-scope attack agents with replay-verified findings. Layers 1–3 also live in code, which is where Deep Code Analysis traces how untrusted tool output reaches a sink.
Why MAESTRO Matters for Agentic AI Security
The agentic AI threat surface is not going to shrink. The models will get more capable. The tool ecosystems will get larger. The supply chain will get more complex. The number of agents per enterprise will multiply, and more of the code they touch will be machine-written; in our own scans, 78% of AI-generated PRs shipped a vulnerability.
MAESTRO is one of the first frameworks built for this and gives the industry a shared vocabulary. The earlier your team adopts it, the faster your pentesters, your threat modellers, and your auditors speak the same language.
The teams that wait will be the ones whose audit reports list “AI security” as a single control. The teams that adopt MAESTRO now will have a layered, evidence-backed, replay-verifiable defence in depth — and that is the bar for proof-driven AppSec in 2026 and beyond.
Frequently Asked Questions
What is the MAESTRO framework?
MAESTRO (Multi-Agent Environment, Security, Threat, Risk, and Outcome) is a threat modeling framework for agentic AI. It splits an agent system into seven layers, from foundation models and data operations up to the agent ecosystem, and lists threats and mitigations for each layer. It extends older methods such as STRIDE, PASTA, and LINDDUN with AI-specific threats like prompt injection, memory poisoning, and MCP tool poisoning.
Is MAESTRO an OWASP or a Cloud Security Alliance framework?
MAESTRO was introduced by Ken Huang on the Cloud Security Alliance blog in February 2025. The OWASP GenAI Security Project’s Agentic Security Initiative then published the Multi-Agentic System Threat Modeling Guide in April 2025, which applies MAESTRO to real multi-agent systems. That is why people often say “OWASP MAESTRO,” but the framework itself originated at CSA.
What are the 7 layers of MAESTRO?
The seven layers are Foundation Models, Data Operations, Agent Frameworks, Deployment and Infrastructure, Evaluation and Observability, Security and Compliance, and Agent Ecosystem. Security and Compliance is a vertical layer that spans all the others. Each layer has its own attack surface, so a MAESTRO threat model reviews them one by one instead of treating the AI agent as a single black box.
How is MAESTRO threat modeling different from STRIDE?
STRIDE classifies threats by type (spoofing, tampering, repudiation, information disclosure, denial of service, elevation of privilege) for traditional software. MAESTRO threat modeling keeps that thinking but organises it around the layers of an agent system, adding threats STRIDE has no slot for: poisoned training data, prompt injection through tools and memory, reasoning-versus-action drift, and multi-agent trust between tools and MCP servers.
How do you use MAESTRO for an agentic AI security pentest?
Start at Layer 1 and work up. For each layer, list the components in scope, map the attack patterns in this guide to them, and confirm the detection signals and mitigations exist. Then test the riskiest paths, usually indirect prompt injection (Layer 2), tool selection (Layer 3), and MCP servers (Layer 7), and keep reproducible evidence for every finding.
Related reading:
- From Alert to Fix: Closing the Loop with Proof-Driven AppSec — the operational loop MAESTRO maps onto
- What Is Deep Code Analysis? — the static-analysis layer that pairs with MAESTRO L1–L3
- 78% of AI-Generated PRs Contain a Vulnerability — the production failure mode MAESTRO L2 / L7 is built to model

